How Hirenix teaches
One chapter. 90 minutes.
Interview-ready.
Every concept starts with a real-world problem — the kind that actually shows up in production code. Nothing to cram; it just clicks. Every question comes with a model answer: exactly what to say in the room, and why. Then an AI mock interview on the same chapter.
- 📖Concept in 5 minutesNo jargon — straight to the point
- 🛠️Real-world problemThe kind production code throws at you
- 💬Model answerExactly what to say in the room
- 🧠FlashcardsRevise in 10 minutes
- 🤖AI mock interviewIt asks follow-ups too
- 📊Weak topicsSee exactly where you're stuck
The difference isn’t the content — it’s the filter. Only what’s actually used in production and actually asked in interviews. Textbook topics the industry never touches don’t make the cut.
Certificates
Learn all 18 topics and earn your Spring Microservices certificate
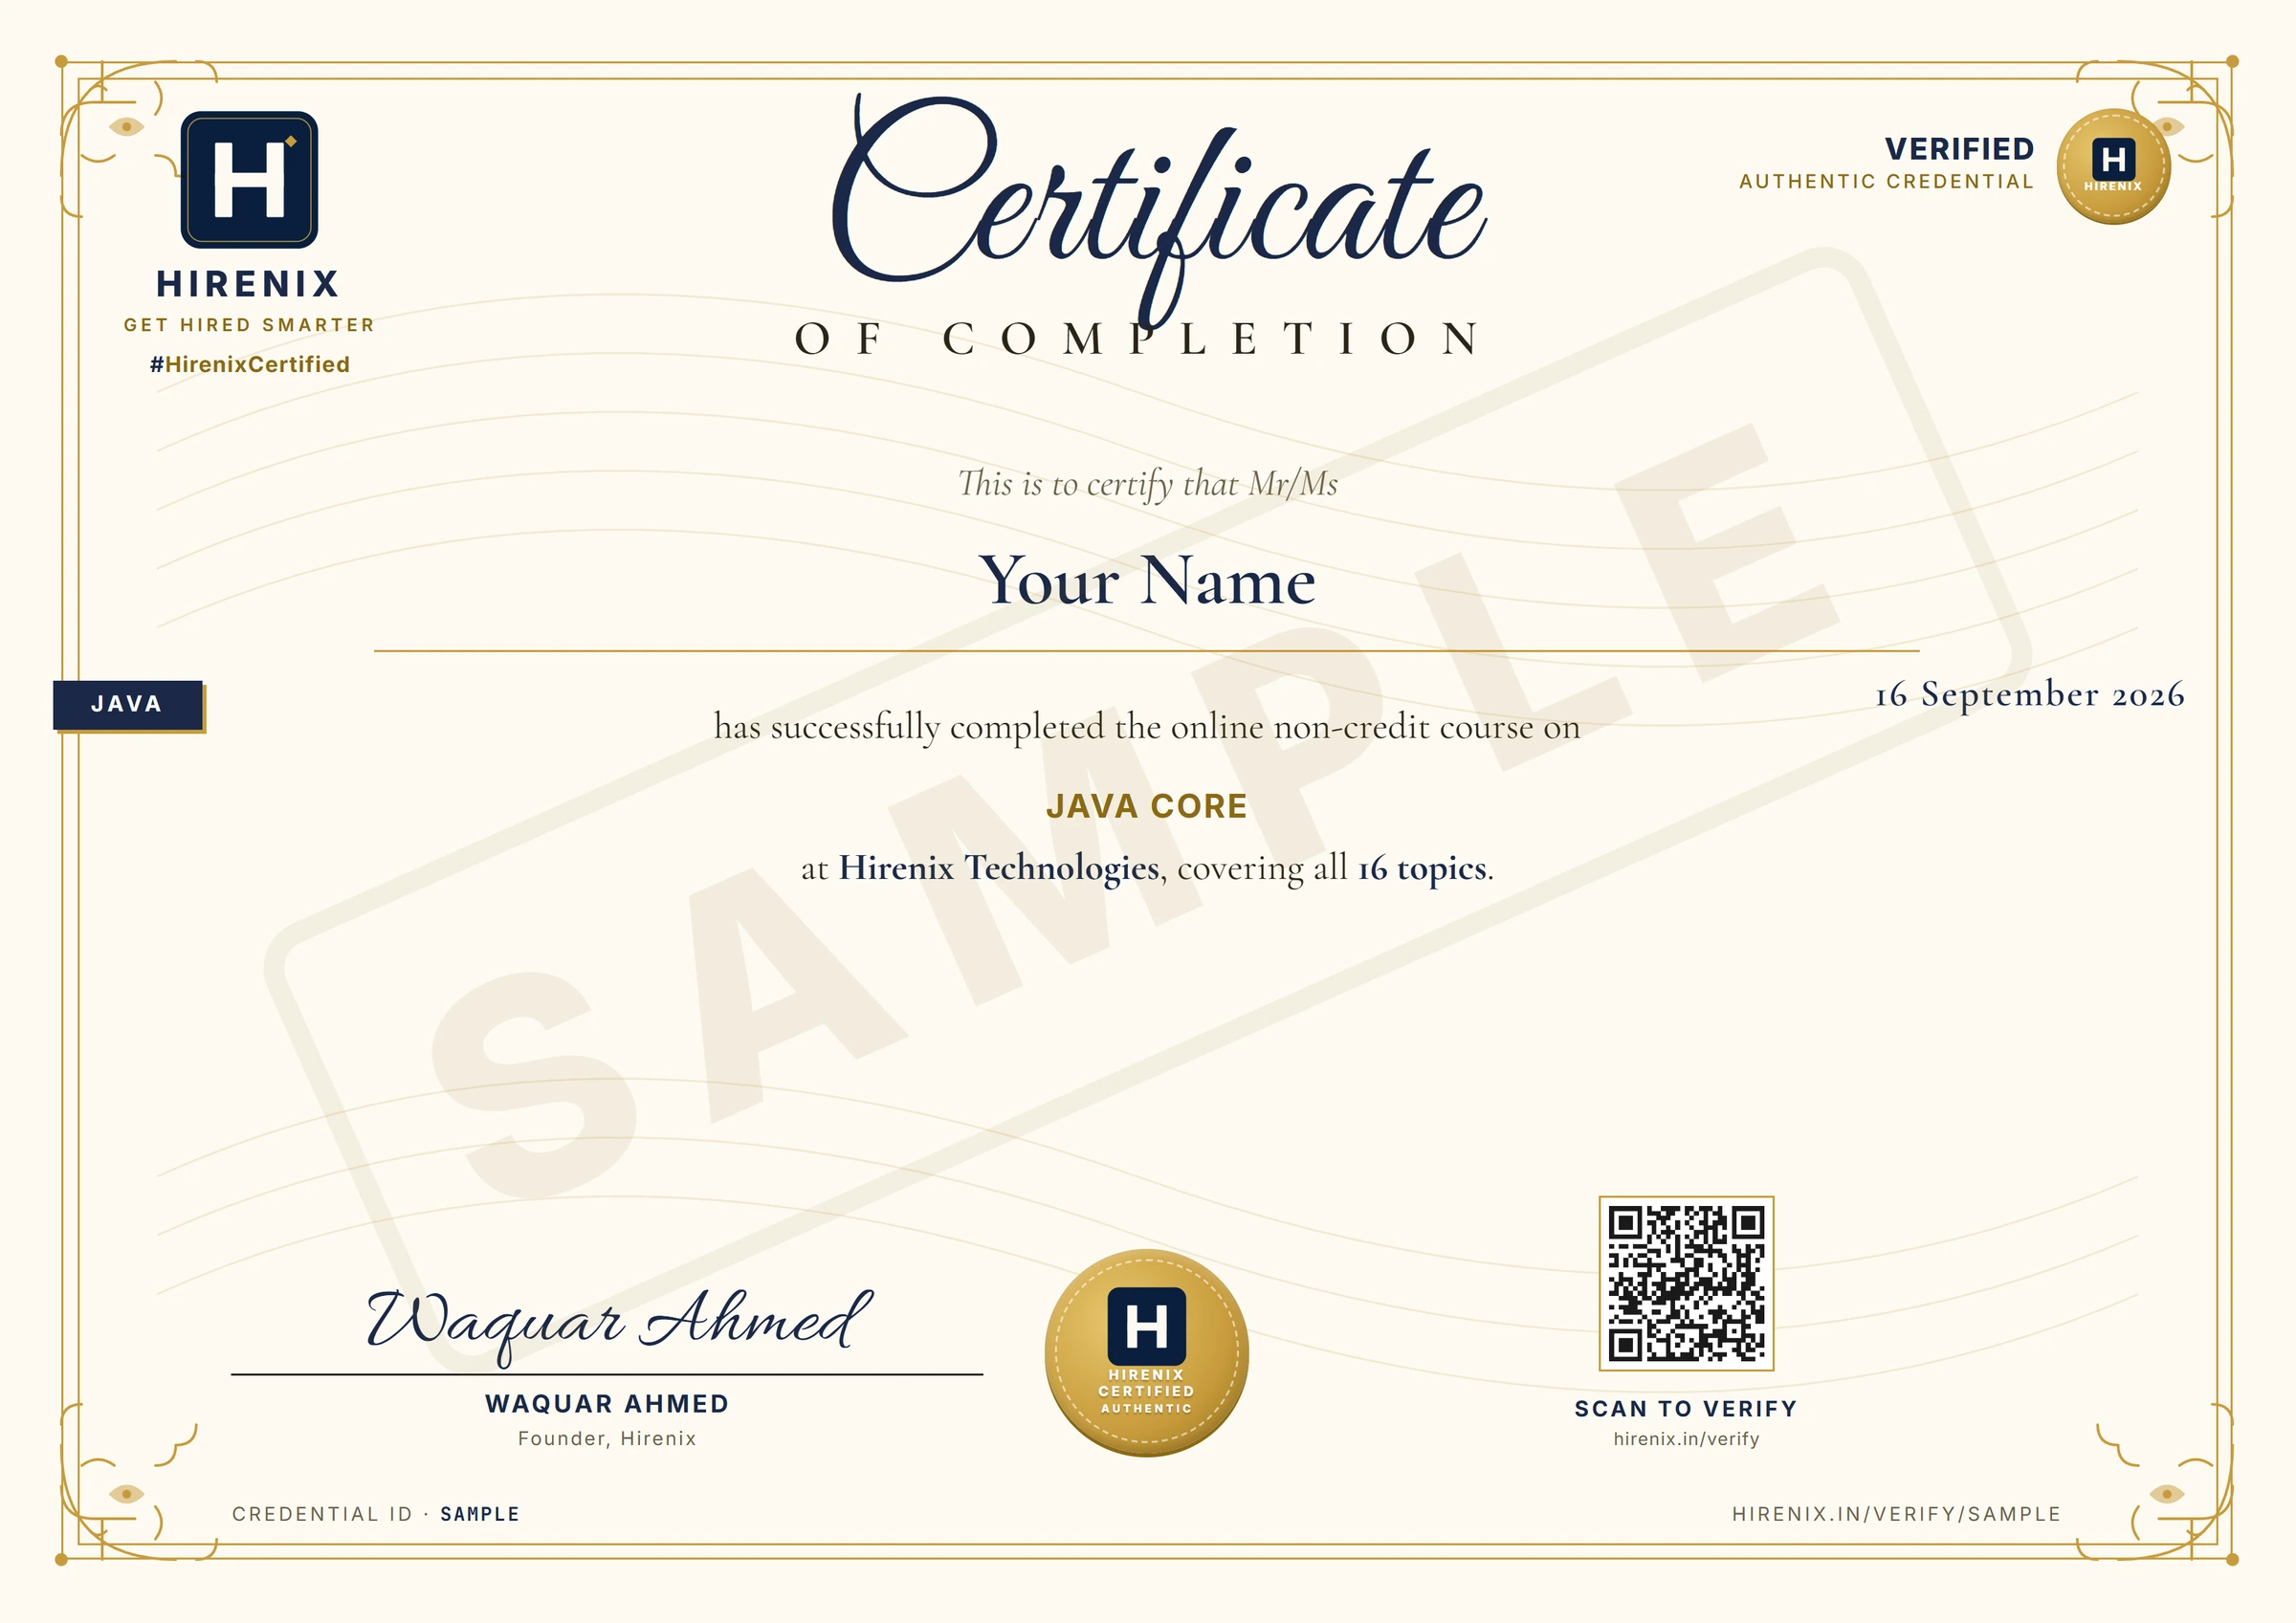
Finish every Spring Microservices topic and a certificate with your name on it is issued instantly. No exam, no waiting. Download it, share it on LinkedIn, and put it on your resume.
Chapter certificate
Your name, the Spring Microservices course and all 18 topics on it.
Stack Mastery certificate
Finish every Java Backend chapter for the Java Backend Stack Mastery certificate.
Anyone can verify it
Each certificate has a QR code and a public link at hirenix.in/verify.
Verified credential
hirenix.in/verify/…
What you’ll learn
- ●Why microservices: what you gain, what you pay, and when a monolith wins
- ●Service-to-service calls: RestClient and HttpExchange interfaces
- Timeouts: how one slow service drags down the callerPro
- Retries and idempotency: when a retry creates a duplicatePro
- Circuit breakers with Resilience4j: closed, open and half-openPro
- Service discovery and client-side load balancing with EurekaPro
- The API gateway: one entry point, routes and filtersPro
- Centralized configuration with Spring Cloud ConfigPro
- Distributed tracing: following one request across servicesPro
- Asynchronous messaging with Kafka: topics, partitions, keys and consumer groupsPro
- Kafka error handling: retries, poison messages and dead-letter topicsPro
- Data consistency across services: the dual-write problem, outbox and sagasPro
- Health probes and deployment: liveness, readiness, containersPro
- Testing service boundaries: stubbed HTTP and an embedded brokerPro
- RecapPro
- ●Project: Split the Job Board into Services
- Project: Make a Flaky Service Call ResilientPro
- Project: Event-Driven Application Alerts with KafkaPro
Free lessons
Why microservices: what you gain, what you pay, and when a monolith wins
"Should we use microservices?" is really a question about what you are willing to pay. Splitting an application into services turns method calls into network calls, one database into several, and one deployment into many. This topic runs the same small job-board feature both ways - as a monolith and as two services - and measures what actually changes.
The setup: one feature, two shapes
The feature is simple: an application for a job needs the job's title. Three Spring Boot apps were started in one JVM on this machine, each with --server.port=0 so each got its own random port:
| App | Owns | How it gets a job title |
|---|---|---|
monolith (MonoApp) |
one H2 database with job and job_application tables |
calls the JobCatalog bean - a method call |
jobs-service (JobsApp) |
its own jobsdb with the job table |
serves GET /jobs/{id} |
| applications-service | its own appsdb with only job_application |
calls jobs-service with RestClient - a network call |
A service here is simply a separately running application with its own port, its own data and an HTTP contract. (All three ran on localhost in one JVM. Real services run in separate processes on separate machines, which only makes every cost below larger. This environment has no Docker and no real network.)
What the measurements showed
1. The network hop is expensive, and noisy. Both paths ran the same H2 query. 5000 calls each, after 2000 warm-up calls, three rounds, in two separate runs. The HTTP path took between 76x and 272x as long as the method call across those six rounds. The spread matters as much as the size: on localhost, with no real network at all, one round was more than three times slower than another. Treat any single latency number as one sample, not a fact.
2. Database-per-service moves integrity out of the database. In the monolith the table has a foreign key, so inserting an application for job 999 failed with JdbcSQLIntegrityConstraintViolationException: Referential integrity constraint violation. In applications-service the same insert was saved (rows=1), even though jobs-service had no job 999 (0). With a database per service there is no foreign key across the boundary. Something in your code - a check call, an event, a clean-up job - now has to do what one constraint did for free.
3. A failure becomes partial. When jobs-service was closed, applications-service was still running (true), but its call failed: ResourceAccessException, root cause HttpHostConnectException ... Connection refused. The monolith has no network in between, but it also has no partial state: if it is down, everything is down. Services give you fault isolation, and in exchange every call site must decide what to do when the other side is gone. Topics 3 to 5 are about exactly that.
4. Independent deployment is real - and needs help. A new jobs-service was started while applications-service kept running (active=true, never restarted). That is the independent deploy benefit. But the new instance got a new random port, and applications-service kept calling the old address and kept getting Connection refused until it was given the new URL. Hard-coded addresses do not survive independent deployment; that is the problem service discovery (topic 6) solves.
Benefits, stated carefully
- Independent deploy and release: a team can ship jobs-service without redeploying applications-service. Shown above.
- Fault isolation: one service down does not stop the others from running. Shown above - but a caller that does not handle the failure still breaks.
- Independent scaling: you can run more copies of just the busy service (topic 6 runs two instances).
- Team ownership: a small team owns one service and its data. This is an organisational benefit; no code run can show it.
The costs
- Network calls instead of method calls: slower, and able to fail in ways a method call cannot (timeouts, connection refused, partial success).
- Distributed data: no joins or foreign keys across services, and no single transaction across two databases (topic 12).
- Operational overhead: more deployments, configuration, monitoring and tracing (topics 7 to 9 and 13).
- Debugging across services: one user request can touch several logs.
When to use microservices: when parts of the system genuinely need to be deployed, scaled or owned independently, the boundaries between them are well understood, and you can afford the operational overhead of running many services.
When NOT to use them: for a new product whose boundaries are still moving, for a small team, or when the main goal is "cleaner code". A well-structured monolith with clear modules is cheaper to run and easier to change, and it can be split later along boundaries you have actually learned. Choosing microservices by default buys every cost above before you need any benefit.
Trade-off: you exchange in-process simplicity (fast calls, one transaction, database-enforced integrity) for independence (deploy, scale and fail separately). The exchange is worth it only when that independence is something you actually use.
// ---- MONOLITH (t1.mono): one app, one database. The catalog is just a bean. ----
@Service
public class JobCatalog {
  private final JdbcTemplate db;
  public JobCatalog(JdbcTemplate db) { this.db = db; }
  public String title(long id) { return db.queryForObject("select title from job where id = ?", String.class, id); }
}
// monodb: job_application.job_id REFERENCES job(id)   <- the database guards the link

// ---- SERVICES: jobs-service (t1.jobs) owns jobsdb and exposes the same question over HTTP ----
@RestController
class JobsController {
  private final JdbcTemplate db;
  JobsController(JdbcTemplate db) { this.db = db; }
  @GetMapping("/jobs/{id}") String title(@PathVariable("id") long id) {
    return db.queryForObject("select title from job where id = ?", String.class, id);
  }
}
// applications-service (t1.apps) owns appsdb: job_application(job_id bigint not null) - no job table, no foreign key

// ---- Main: all three apps started in one JVM, each on its own random port ----
var mono = new SpringApplicationBuilder(MonoApp.class).run("--server.port=0", "--spring.datasource.url=jdbc:h2:mem:monodb", ...);
var jobs = new SpringApplicationBuilder(JobsApp.class).run("--server.port=0", "--spring.datasource.url=jdbc:h2:mem:jobsdb", ...);
var apps = new SpringApplicationBuilder(ApplicationsApp.class).run("--server.port=0", "--spring.datasource.url=jdbc:h2:mem:appsdb", ...);
RestClient http = apps.getBean(RestClient.Builder.class).baseUrl("http://localhost:" + jobsPort).build();

// 1. same question, two shapes
catalog.title(7);                                          // method call
http.get().uri("/jobs/7").retrieve().body(String.class);   // network call

// 2. 5000 calls each after 2000 warm-up, timed with System.nanoTime(), 3 rounds

// 3. who guards the reference?
monoDb.update("insert into job_application(job_id, candidate) values (999, 'asha')");
appsDb.update("insert into job_application(job_id, candidate) values (999, 'asha')");

// 4. stop jobs-service, call it again
jobs.close();
http.get().uri("/jobs/7").retrieve().body(String.class);

// 5. start a new jobs-service (new random port); applications-service is not restarted
var jobs2 = new SpringApplicationBuilder(JobsApp.class).run("--server.port=0", ...);
Service-to-service calls: RestClient and HttpExchange interfaces
Once an application is split, one service has to call another over HTTP. In Spring Boot 3.5 there are several clients that can do it, and they look interchangeable until something goes wrong. This topic calls the same jobs-service from three client styles and shows what each one returns on success, on 404 and 500, and when a timeout property is set.
The setup
jobs-service has GET /jobs/{id} (returns a Job record, 404 for an unknown id, 500 for id 500), POST /jobs (returns 201 with a Location header) and GET /slow?ms=.... A caller app was started with --spring.http.client.read-timeout=1s. Everything ran on localhost on Boot 3.5.16 and Spring Cloud OpenFeign 4.3.3.
A. RestClient: the fluent client
RestClient is a synchronous client with a fluent API: get(), uri(...), retrieve(), then body(...) or toEntity(...). The runs showed:
body(Job.class)turned the JSON intoJob[id=7, title=Java Developer, company=Acme].body(String.class)returned the raw JSON.toEntity(Job.class)gave the status and headers as well:201 CREATED Location=/jobs/101.- On
404,retrieve()threwHttpClientErrorException$NotFound. On500it threwHttpServerErrorException$InternalServerError. Both carried the status and the response body. Notice what the body did not carry: the reason textjob 404 not foundfrom the server was not in Boot's default error JSON. Do not plan to read the other service's error message out of that body unless the service puts it there. onStatus(...)replaced the default: the 404 became your ownNoSuchElementException, which is how you turn a remote status into a domain exception.exchange(...)gave raw access and threw nothing:status 404, nothing thrown. Use it when a 404 is a normal answer, not an error.
B. @HttpExchange: an interface instead of calls
@HttpExchange("/jobs") with @GetExchange and @PostExchange describes the remote API as a Java interface. HttpServiceProxyFactory with RestClientAdapter.create(rc) built an implementation at runtime - a JDK dynamic proxy (jdk.proxy2.$Proxy120). Calls behaved exactly like the RestClient underneath: jc.get(7) returned the record, jc.create(...) returned 201 CREATED, and jc.get(404) threw the same HttpClientErrorException$NotFound. The interface is only a nicer front; the error handling and configuration come from the RestClient you pass in.
C. OpenFeign: @FeignClient
@EnableFeignClients plus @FeignClient(name = "jobs-service", url = "${jobs.url}") on an interface that uses Spring MVC annotations (@GetMapping, @PathVariable) produced a bean that was also a JDK proxy. It returned the same Job on success, but the exceptions are different: feign.FeignException$NotFound for 404 and feign.FeignException$InternalServerError for 500. Code that catches HttpClientErrorException will not catch those. OpenFeign is part of Spring Cloud, not of Spring Framework; @HttpExchange needs no extra project.
D. One property, four clients - the result that matters most
With spring.http.client.read-timeout=1s set, each client called GET /slow?ms=1500:
| Client | Result |
|---|---|
RestClient built from the injected RestClient.Builder |
ResourceAccessException, root SocketTimeoutException, after about 1 s |
RestClient.create(url) |
waited and returned the slow reply (about 1.5 s) |
new RestTemplate() |
waited and returned the slow reply |
@FeignClient |
waited and returned the slow reply |
The Boot property was applied only to the client built from Boot's RestClient.Builder. A client created with RestClient.create() or new RestTemplate() never passed through Boot's configuration, and OpenFeign did not use that property either (it has its own client settings, which this run did not test). Topic 9 shows the same split for tracing headers. The habit to build: inject RestClient.Builder and build from it; do not call RestClient.create() in application code.
RestTemplate, WebClient, RestClient
RestTemplatestill worked on Spring Framework 6.2.19 (row D). According to the Spring documentation it is the older template-style API, and new synchronous code is pointed atRestClient.WebClientis the reactive client fromspring-webflux. That module is not on this environment's classpath, so nothing aboutWebClientwas run here; per the documentation, choose it when the calling application is itself reactive.RestClient(Spring Framework 6.1+, per the documentation) gives a fluent API on the same blocking model asRestTemplate.
When to use which: RestClient from the injected builder for straightforward calls in a servlet application; an @HttpExchange interface when one remote API is called from many places and you want a typed contract; OpenFeign when the codebase already uses it with Spring Cloud features built around it.
When NOT to: do not use RestClient.create() or new RestTemplate() in application code - measured above, they silently ignore Boot's client settings. Do not mix Feign and RestClient exceptions in one error-handling layer without mapping them; they are different types.
Trade-off: declarative interfaces (@HttpExchange, Feign) remove boilerplate and make calls look like local method calls. That is also their risk - a line like jc.get(7) hides a network call that can time out, return 404 or fail halfway, exactly as topic 1 showed.
// ---- jobs-service (t2.jobs): the service being called ----
@GetMapping("/jobs/{id}") Job get(@PathVariable("id") long id) {
  if (id == 500) throw new IllegalStateException("database unavailable");
  Job j = jobs.get(id);
  if (j == null) throw new ResponseStatusException(HttpStatus.NOT_FOUND, "job " + id + " not found");
  return j;
}
@PostMapping("/jobs") ResponseEntity<Job> create(@RequestBody Job in) { ... return ResponseEntity.created(URI.create("/jobs/" + j.id())).body(j); }
@GetMapping("/slow") String slow(@RequestParam("ms") long ms) throws InterruptedException { Thread.sleep(ms); return "slow reply after " + ms + " ms"; }

// ---- caller (t2.caller), started with --spring.http.client.read-timeout=1s ----
@SpringBootApplication
@EnableFeignClients
public class CallerApp { }

// A. RestClient from Boot's injected builder
RestClient rc = ctx.getBean(RestClient.Builder.class).baseUrl(jobsUrl).build();
rc.get().uri("/jobs/{id}", 7).retrieve().body(Job.class);
rc.post().uri("/jobs").body(new Job(0, "SRE", "Beta")).retrieve().toEntity(Job.class);
rc.get().uri("/jobs/{id}", 404).retrieve().body(Job.class);                       // 4xx
rc.get().uri("/jobs/{id}", 500).retrieve().body(Job.class);                       // 5xx
rc.get().uri("/jobs/{id}", 404).retrieve()
    .onStatus(s -> s.value() == 404, (req, res) -> { throw new NoSuchElementException("no such job"); })
    .body(Job.class);
rc.get().uri("/jobs/{id}", 404).exchange((req, res) -> "status " + res.getStatusCode().value() + ", nothing thrown");

// B. declarative interface on top of the same RestClient
@HttpExchange("/jobs")
public interface JobsHttpClient {
  @GetExchange("/{id}") Job get(@PathVariable("id") long id);
  @PostExchange ResponseEntity<Job> create(@RequestBody Job job);
}
JobsHttpClient jc = HttpServiceProxyFactory.builderFor(RestClientAdapter.create(rc)).build().createClient(JobsHttpClient.class);

// C. OpenFeign (spring-cloud-openfeign 4.3.3)
@FeignClient(name = "jobs-service", url = "${jobs.url}")
public interface JobsFeignClient {
  @GetMapping("/jobs/{id}") Job get(@PathVariable("id") long id);
  @GetMapping("/slow") String slow(@RequestParam("ms") long ms);
}

// D. one property, four clients: GET /slow?ms=1500
rc.get().uri("/slow?ms=1500")...                    // built from the injected Builder
RestClient.create(jobsUrl).get().uri("/slow?ms=1500")...
new RestTemplate().getForObject(jobsUrl + "/slow?ms=1500", String.class);
feignClient.slow(1500);
Project: Split the Job Board into Services
In Ch9 the job board was one Spring Boot application with one database; Ch10 secured it and Ch11 tested it. This project splits it into two services - jobs-service owns jobs, applications-service owns applications - and runs every decision the split forces. Both services ran on this machine as separate Spring Boot apps with their own H2 databases, on Spring Boot 3.5.16.
The split
| jobs-service | applications-service | |
|---|---|---|
| owns | job table (id, title, status) |
application table (candidate, job_id) |
| exposes | GET /jobs/{id}, later GET /jobs?ids=... |
POST /applications, GET /applications |
| knows about the other | nothing | an @HttpExchange interface JobsApi with only the fields it needs |
The boundary follows ownership: whoever changes a job's status owns the job table. applications-service keeps only job_id and has no job table - database-per-service from topic 1.
JobsApi is built from Boot's injected RestClient.Builder (topic 2), with connect-timeout and read-timeout set to 1 s (topic 3). The client factory is set to jdk so the HTTP client does not resend a request on its own (topic 3's hidden retry).
Step 1: the foreign key becomes a network call
In the monolith a foreign key and a status check in the same transaction protected applications. Now POST /applications asks jobs-service first:
- job 7 (open) ->
201 applied to Java Developer - job 999 (does not exist) ->
422 job 999 does not exist- the remote404is translated into this service's own answer, not passed through as an error - job 8 (closed) ->
409 job 8 is CLOSED
This check is not atomic: a job could close between the check and the insert. The monolith's single transaction prevented that; here you accept a small window, or you handle it later with events (topic 12 and project 18).
Step 2: N+1 over HTTP
"My applications" needs job titles, which applications-service does not have. The first version called jobs-service once per application: 5 applications -> 5 calls. With each call taking 150 ms, the page took 847 ms.
Adding a batch endpoint GET /jobs?ids=... returned the same five titles with 1 call and 173 ms. This is Ch9's N+1 problem again, only each "query" is now a network round trip. Design the provider's API for how consumers actually read, and measure call counts, not just response bodies. (Timings from a single run on localhost; the call counts are the reliable part.)
Step 3: jobs-service is slow
jobs-service was made to take 3 s per call.
- With the 1 s read timeout:
503 jobs-service unavailable, try again laterafter 1020 ms. - Break 1 - no timeout properties: the user waited 3035 ms and got
201. It worked, but every applications-service thread handling an apply was held for 3 s. Under real traffic that is topic 3's cascading failure.
Step 4: jobs-service is down
- Handled:
503 jobs-service unavailable, try again laterin 25 ms. Connection refused is fast, and the user gets a clear, retryable answer. - Break 2 - the exception is not handled:
500 Internal Server Errorin 29 ms. To the user and to any monitoring, applications-service now looks broken, although it is jobs-service that is down. - In both cases
applications rows for meera: 0. Nothing was saved without a validated job, so the data stayed consistent - the cost is that users cannot apply while jobs-service is down.
Decisions this project leaves you with
- Availability vs strictness. Step 4 chose "reject when unsure". The alternative - accept the application as
PENDINGand validate asynchronously (topic 12's saga) - keeps applying available during an outage, at the cost of later rejections. - Data you copy vs data you call for. Step 2 could also be solved by keeping a local, event-updated copy of job titles in applications-service: no call at read time, but eventually consistent titles.
- Who translates errors. applications-service must turn jobs-service's
404, timeouts and connection failures into its own API's answers (422,503). Leaking the other service's errors, or letting them become500s, spreads one service's problems across the system.
The shape to take away
Splitting a monolith does not remove any rule; it moves each rule to a network call, an event or an accepted inconsistency. For every rule that used to be a foreign key, a join or a transaction, decide explicitly which of the three it becomes - and put a timeout and error translation on every call you add.
// ---- jobs-service: owns the job table (its own H2 database) ----
@GetMapping("/jobs/{id}")
Job one(@PathVariable("id") long id) throws InterruptedException {
  return query("where id = ?", id).stream().findFirst()
      .orElseThrow(() -> new ResponseStatusException(HttpStatus.NOT_FOUND, "job " + id));
}
@GetMapping("/jobs")                                    // batch endpoint, added in step 2
List<Job> many(@RequestParam("ids") List<Long> ids) throws InterruptedException { ... "where id in (?, ?, ...)" ... }
// query(...) counts HITS and can sleep DELAY_MS to simulate a slow service

// ---- applications-service: owns the application table (its own H2 database, no job table) ----
public interface JobsApi {                               // only the fields this service needs
  record JobView(long id, String title, String status) { }
  @GetExchange("/jobs/{id}") JobView job(@PathVariable("id") long id);
  @GetExchange("/jobs") List<JobView> jobs(@RequestParam("ids") List<Long> ids);
}

@Bean
JobsApi jobsApi(RestClient.Builder builder, Environment env) {       // built from Boot's builder: timeouts apply
  RestClient rc = builder.baseUrl(env.getProperty("jobs.url")).build();
  return HttpServiceProxyFactory.builderFor(RestClientAdapter.create(rc)).build().createClient(JobsApi.class);
}

@PostMapping("/applications")
ResponseEntity<String> apply(@RequestBody ApplyRequest req) {
  JobsApi.JobView job;
  try {
    job = jobs.job(req.jobId());
  } catch (HttpClientErrorException.NotFound e) {
    return ResponseEntity.unprocessableEntity().body("job " + req.jobId() + " does not exist");
  } catch (RestClientException e) {
    if (!handleFailures) throw e;                                      // break 2 sets demo.handle-failures=false
    return ResponseEntity.status(HttpStatus.SERVICE_UNAVAILABLE).body("jobs-service unavailable, try again later");
  }
  if (!"OPEN".equals(job.status())) return ResponseEntity.status(HttpStatus.CONFLICT).body("job " + job.id() + " is " + job.status());
  db.update("insert into application(candidate, job_id) values (?, ?)", req.candidate(), req.jobId());
  return ResponseEntity.status(HttpStatus.CREATED).body("applied to " + job.title());
}

@GetMapping("/applications")                             // v1: one jobs-service call per application
List<String> mine(@RequestParam("candidate") String candidate) {
  return db.queryForList("select job_id from application where candidate = ? order by id", Long.class, candidate)
      .stream().map(id -> jobs.job(id).title()).toList();
}

@GetMapping("/applications/v2")                          // v2: one batch call
List<String> mineBatched(@RequestParam("candidate") String candidate) {
  List<Long> ids = db.queryForList("select job_id from application where candidate = ? order by id", Long.class, candidate);
  Map<Long, String> titles = jobs.jobs(ids).stream().collect(Collectors.toMap(JobsApi.JobView::id, JobsApi.JobView::title));
  return ids.stream().map(titles::get).toList();
}

// applications-service runs with --spring.http.client.connect-timeout=1s --spring.http.client.read-timeout=1s
//                                --spring.http.client.factory=jdk   (no hidden 503/429 resend, topic 3)
// break 1: a second applications-service started with no timeout properties
Spring Microservices interview questions & answers
10 sample questions below — 204+ in the full bank inside.
When is Kafka the wrong tool for communication between services?
When the caller needs the answer immediately, and as a hidden request-reply mechanism - you get all the complexity of messaging and still wait. Also when you cannot handle at-least-once delivery and duplicates, or cannot operate a broker cluster. For a single consumer and low volume, a simpler mechanism may do.
In simple terms: Balanced view.
What is the difference between an instance shutting down gracefully and crashing, from the registry's point of view?
A graceful shutdown deregisters the instance, so callers stop using it quickly - in the chapter the caller showed instances=1 right after close() and sent all calls to the remaining instance. A crash sends no goodbye; the entry stays until its lease expires without heartbeats, and callers keep trying it meanwhile. (The lease-expiry path of a truly crashed process was not run here.)
In simple terms: Graceful paths are the easy case.
Why did each step of the project start with a successful warm-up search?
To start every configuration from the same state: an established connection, and - once a fallback existed - a last good result to fall back to. It also counted as one recorded success in the circuit breaker, which is part of why the breaker opened after the first failed search's attempts in outage and slow modes. Setup details like this change measured numbers, so they belong in the write-up.
In simple terms: Experimental hygiene.
What are the main benefits of microservices?
Independent deploy and release (a team ships its service without redeploying others), fault isolation (one service down does not stop the others from running), independent scaling (run more copies of only the busy service) and team ownership (a small team owns a service and its data). The demo showed two of them: applications-service kept running while jobs-service was closed, and a new jobs-service was deployed without restarting applications-service.
In simple terms: List them, then show you know each one has a condition attached.
What does idempotent mean, and which HTTP methods are idempotent?
An operation is idempotent if doing it once or many times leaves the same final state. By HTTP's definition GET, PUT and DELETE are idempotent and POST is not - but the definition is a contract the handler must implement. In the chapter a PUT storing the application under the candidate's name received 3 requests and left 1 row, while a POST under identical timings left 3 rows.
In simple terms: Definition plus the measured control.
Explain topic, partition, offset, producer and consumer in Kafka.
A topic is a named log, split into partitions. A producer appends a record to one partition, where it gets the next offset - the demo's job-7 records landed at offsets 0, 2 and 4 of partition 0. A consumer reads a partition from an offset. A broker stores the partitions; the chapter ran one broker inside the JVM, so replication was not part of the run.
In simple terms: Definitions tied to measured offsets.
What do the StripPrefix and AddRequestHeader filters do?
StripPrefix=1 removes the first path segment before forwarding: a client call to /api/jobs/7 reached the backend as GET /jobs/7. AddRequestHeader=X-Via, gateway adds a header the client never sent; the backend saw X-Via=gateway. Filters apply only to their own route - on a route without that filter the backend saw X-Via=null.
In simple terms: Measured before/after of each filter.
Summarise the resilience stack the project ended with, in order.
A timeout on the call itself; a circuit breaker around the call; a retry outside the breaker that retries only temporary errors and not CallNotPermittedException; and a fallback when everything else fails. After each addition all three failure modes were measured again.
In simple terms: A compact interview answer.
What is an API gateway and why do microservices use one?
A single entry point for external clients. Clients call the gateway, which routes each request to the right service and applies cross-cutting rules such as authentication, headers and rate limits on the way. It hides internal service addresses from clients and gives one place for edge policies. In the chapter an API-key check at the gateway answered 401 while the backend received 0 hits.
In simple terms: Definition plus the measured benefit.
Why would a microservices system use centralized configuration?
With many services and environments, copies of properties files drift apart and a shared change means many redeploys. A Config Server keeps configuration in one reviewed, versioned place, each service reads its own slice at startup, and selected values can be refreshed at runtime. In the chapter one change to jobs-service.properties reached a running client after POST /actuator/refresh, without a redeploy.
In simple terms: Problem first, then the tool.
194+ more Spring Microservices questions inside
Start free to read the first 10 with model answers and take a voice mock interview. The full question bank comes with Pro.
Start free